To improve network latency in colocation, start by measuring where the delay actually occurs. Establish normal round-trip times, trace the routes between your workload and its users or dependencies, check for congestion and packet loss, and compare available carrier paths before changing infrastructure.
More bandwidth does not automatically mean lower latency. Neither does choosing the geographically closest data centre. The cause may be an indirect carrier route, an overloaded link, unnecessary network hops or an application dependency located much further away than the server itself.
The useful question is not simply whether latency is high. It is where the extra delay begins.
Establish a latency baseline before changing anything
One ping result is not enough to diagnose a network problem.
Latency changes according to traffic levels, routing, source location and time of day. Before replacing a circuit, changing carrier or considering another colocation location, establish how the important network paths normally behave.
Measure from the endpoints that actually interact with the workload. Depending on your architecture, these might include:
offices or user locations
cloud environments
another data centre
disaster recovery infrastructure
remote application components
external services used regularly by the application
Do not look at average latency alone.
| Measurement | What it helps you understand |
|---|---|
| Latency | How long data takes to travel between endpoints |
| Jitter | How much that delay varies |
| Packet loss | How much traffic fails to arrive |
| Bandwidth utilisation | Whether a connection is approaching capacity |
| Route path | Which networks and locations the traffic crosses |
The IETF's <u>standard for measuring one-way network delay</u> highlights an important limitation of relying solely on round-trip measurements. Forward and return traffic can follow different paths, so a single RTT figure may hide differences between the two directions.
Record the normal range now, so you have something concrete to compare when latency changes later.
Find where the additional delay begins
Once you know what normal looks like, break the network journey into smaller sections.
If users report that an application hosted in colocation feels slow, the delay could exist between:
the user and their internet provider
access and upstream networks
two carrier networks
the carrier and the data centre
the data-centre edge and your equipment
the application and another service it depends on
the server and its storage or database
Traceroute and similar diagnostic tools can help show the path packets take and where response times begin to change.
However, one slow-looking hop does not necessarily identify a fault. Network devices can treat diagnostic traffic differently from production traffic, so isolated traceroute results need context.
Look for repeatable behaviour across different times, endpoints and network paths.
For an external perspective, <u>RIPE Atlas</u> provides distributed internet measurement infrastructure capable of running tests such as ping and traceroute from probes in different networks.
That can be useful when you need to understand how a colocated service appears from several external locations rather than only from your own network.
Check the route before increasing bandwidth
High latency and insufficient bandwidth are different problems.
If a high-capacity circuit is lightly utilised, buying an even larger one will not shorten the distance packets travel or correct an unnecessarily indirect route.
Start by looking at where traffic actually goes.
Internet traffic does not simply follow the geographically shortest route. The <u>BGP-4 standard</u> defines a route-selection process in which available paths can be influenced by routing attributes and configured policy.
Alternative text: Network monitoring screens showing traffic routes and latency trends.
In practice, the route can be affected by:
carrier peering arrangements
BGP routing decisions
upstream provider changes
network policies
where different networks exchange traffic
This is why geographic distance should not be used as the only measure of likely network performance.
A facility that appears slightly further away geographically may have a more direct network path to your users or supporting infrastructure than a closer facility.
If location is part of the decision, our guide to <u>where to colocate</u> looks at geography alongside connectivity, power and cooling.
For latency-sensitive workloads, test the relevant network paths rather than choosing a facility from a map alone.
Compare carrier paths rather than carrier names
If the measurements point towards the upstream network, carrier choice becomes more important.
A carrier-neutral environment provides access to multiple network providers, which can make it easier to compare routes according to the requirements of the workload.
That does not mean adding another carrier automatically improves latency.
When comparing carriers, test whether the alternative route:
reaches important user networks more directly
avoids a consistently problematic upstream path
provides better routing to another site
has more suitable peering for important platforms
behaves more consistently during busy periods
Our guide to <u>carrier-neutral data centre benefits</u> covers provider choice and network flexibility in more detail.
For latency optimisation specifically, carrier selection should follow the measurements. A recognisable provider name matters less than the path your traffic actually takes.
Remove network hops you do not need
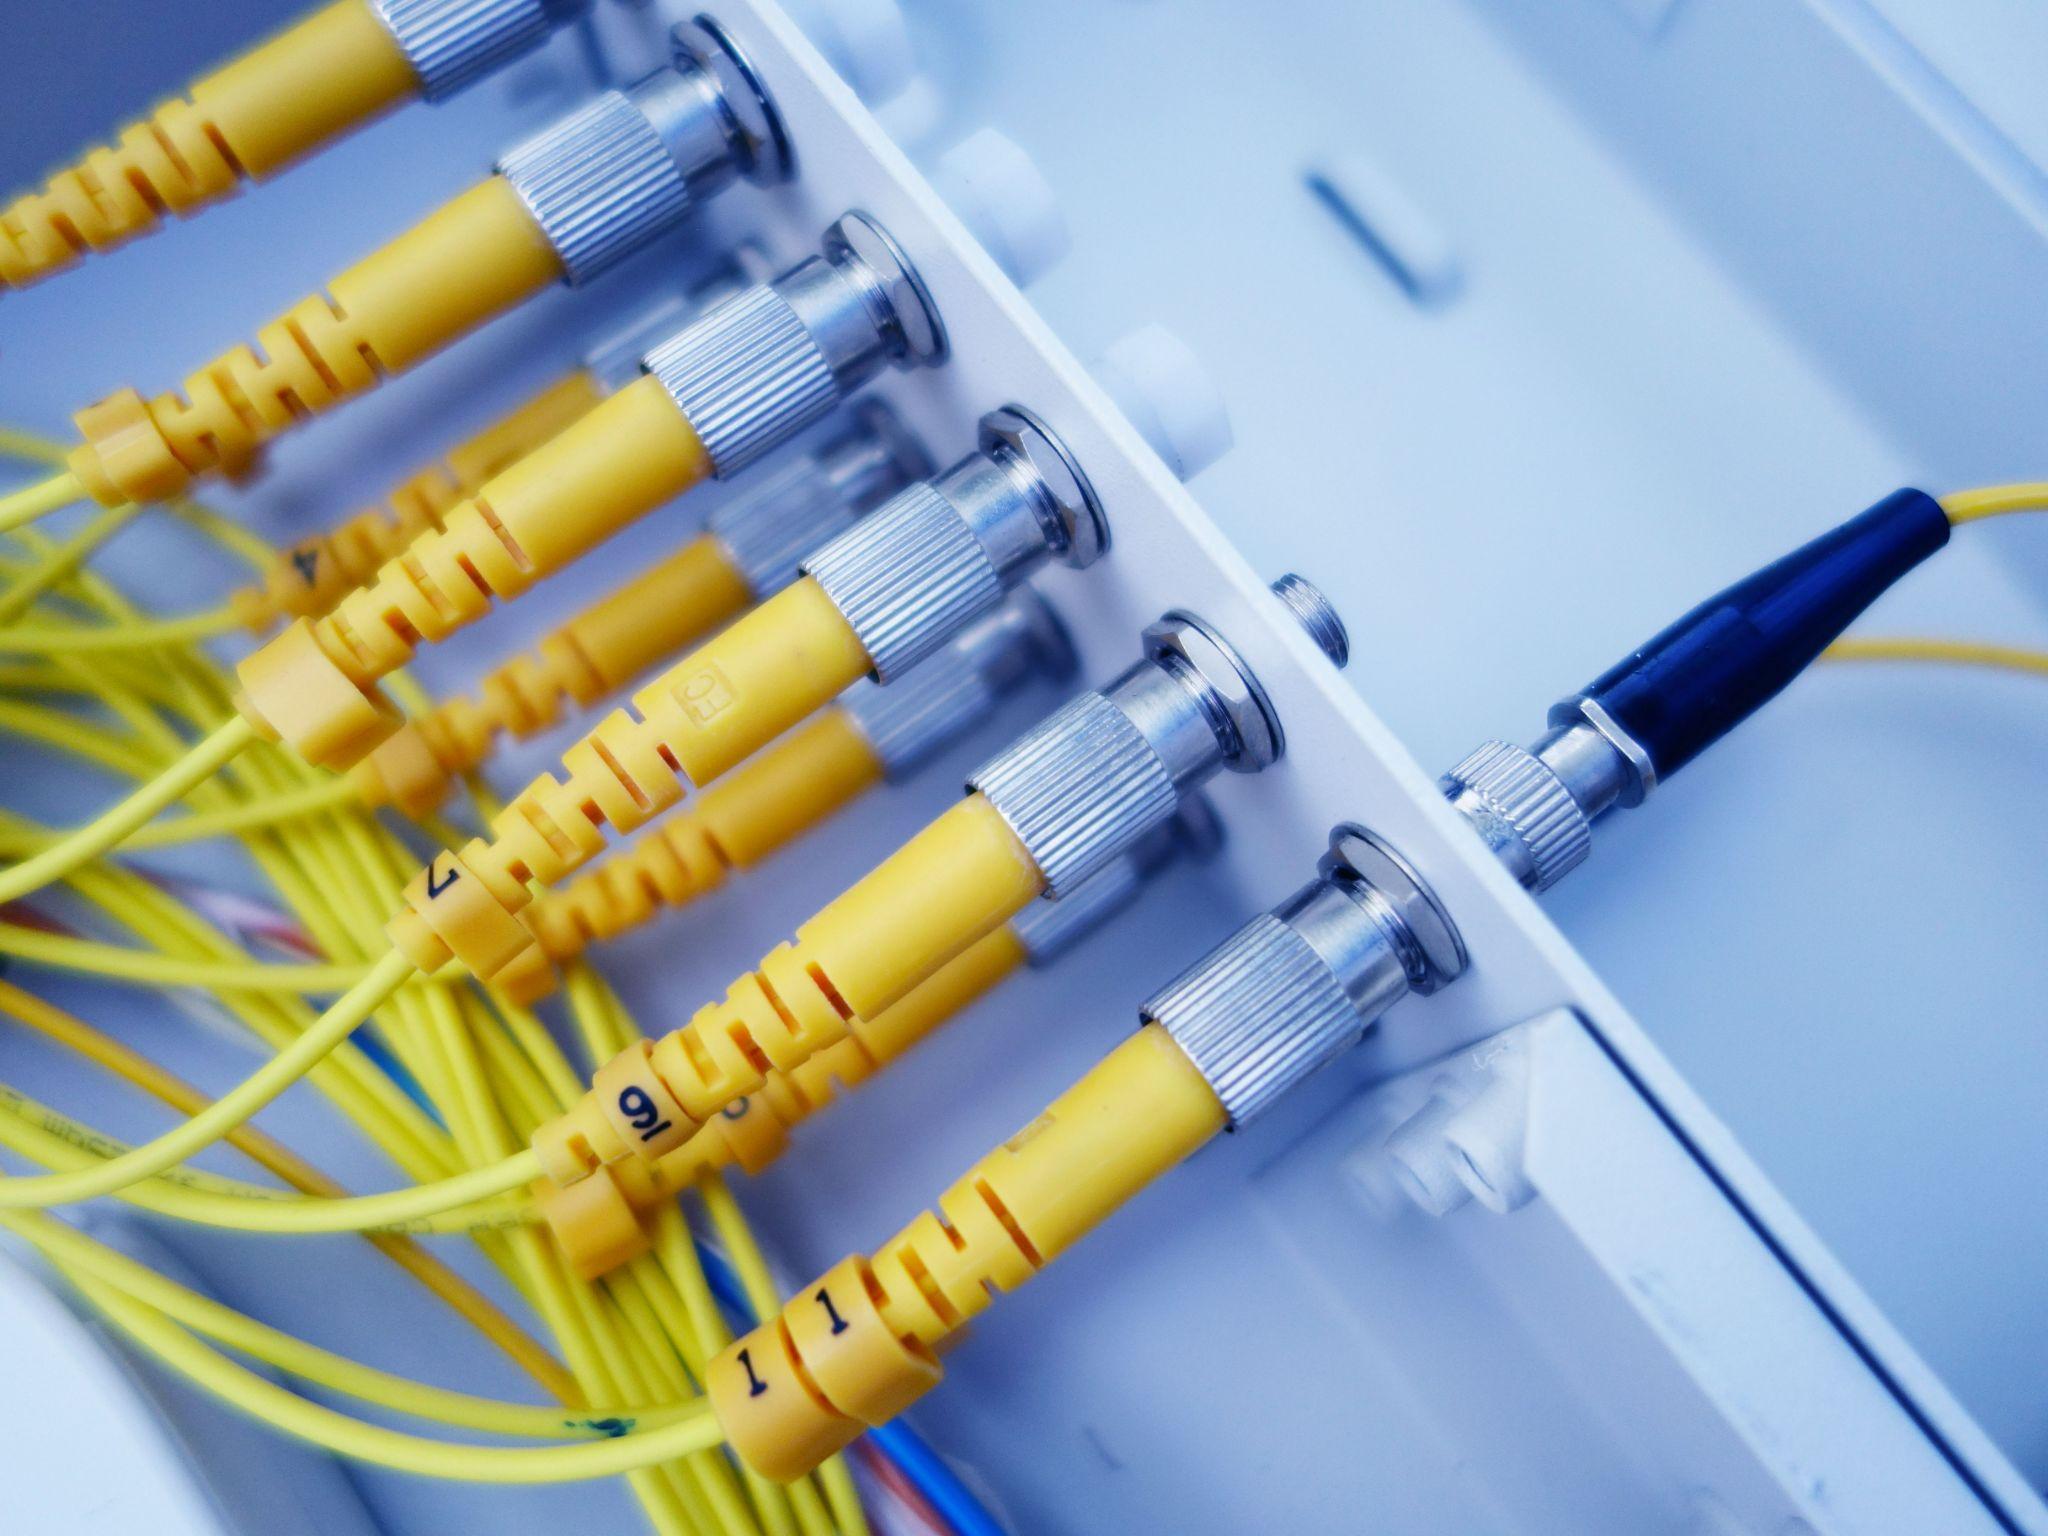
Some latency problems are architectural rather than capacity-related.
If two systems communicate constantly but the traffic has to leave a facility, traverse public networks and return through another path, there may be more distance and more intermediary networks involved than the workload requires.
Where appropriate connectivity is available, a private cross-connect can provide a more direct physical connection between infrastructure.
Alternative text: Fibre optic cables connected to network infrastructure in a data centre.
Private connectivity can also be relevant where systems regularly exchange traffic between particular sites or platforms and predictable routing matters.
Our Connectivity Services include carrier-neutral network access, dedicated internet connectivity and private cross-connects. These options become relevant when your measurements identify an indirect public route, carrier dependency or unnecessary network hop as part of the latency problem.
If your testing points towards the way the infrastructure is connected rather than the servers themselves, explore our <u>Connectivity Services</u> page to see the connection options available for a colocation deployment.
A direct connection is not automatically the right answer. Compare it with the route your traffic currently takes and determine whether the additional network path is actually contributing to delay.
Check whether congestion is increasing latency
Latency that increases during busy periods deserves a different investigation from latency that remains consistently high.
When a link or network device approaches capacity, packets may spend longer waiting in queues before they can be transmitted.
Check for:
high interface utilisation
increasing jitter
packet loss during peak periods
queue drops
interface errors
retransmissions
latency increasing alongside traffic volume
This is where additional bandwidth may genuinely help.
But identify where the congestion sits first.
Increasing the capacity of your own internet connection will not resolve a bottleneck elsewhere in the path. Equally, switching carriers will not solve an overloaded interface inside your own infrastructure.
Compare traffic utilisation and latency across the same period. If both begin rising together, you have stronger evidence that capacity or queueing is contributing to the problem.
Separate network latency from application delay
A slow application does not necessarily mean the network is slow.
A request might cross the network quickly and then spend most of its time waiting for a database, storage system, external API or application process.
That distinction matters because changing network infrastructure cannot fix delay created elsewhere in the application stack.
Depending on the system, compare measurements such as:
DNS lookup time
TCP connection time
TLS negotiation time
network round-trip time
time to first byte
database response time
complete application response time
If network RTT remains stable while application response times increase, investigate the application or its dependencies before changing the colocation network.
This becomes particularly important in hybrid architectures.
An application may run in colocation while its database, object storage, authentication platform or API dependencies remain in a cloud environment or another facility. The server itself can have excellent local connectivity while the overall application still depends on a slower remote path.
Monitor changes rather than waiting for an outage
Latency monitoring is much more useful when you already know what normal behaviour looks like.
A baseline allows you to identify gradual changes such as:
average RTT increasing over time
peak-hour latency becoming less predictable
jitter increasing on one path
a routing change appearing after a provider modification
packet loss developing on a previously stable connection
backup connectivity performing differently from the preferred route
Historical measurements also make troubleshooting less subjective.
Instead of relying on reports that an application "feels slower", you can identify when the behaviour changed and compare that point with routing changes, firewall modifications, capacity increases or application releases.
That tells you whether to keep looking at the network or move the investigation into the application stack.
Do not remove resilience just to reduce latency
A short network path can be attractive, but do not remove redundancy simply to shave a few milliseconds from the preferred route.
A direct connection might perform well while leaving the workload dependent on one carrier, one circuit or one network device.
Latency and resilience therefore need to be assessed together, without treating them as the same objective.
Ask two separate questions:
How efficiently does traffic travel during normal operation?
What happens if that preferred path becomes unavailable?
If availability and failover are the larger issue, our separate guide to <u>improving network resilience in data centres</u> covers route diversity, failover and observability in greater detail.
For latency optimisation, the aim is to improve the normal traffic path without creating an architecture that only performs well while every component is available.
A practical order for diagnosing colocation latency
When network performance is worse than expected, work through the evidence before making infrastructure changes:
1. Measure from the actual users, systems or locations affected.
2. Establish normal and peak-period latency.
3. Compare jitter and packet loss alongside RTT.
4. Trace the route traffic actually takes.
5. Identify where additional delay begins.
6. Check interfaces and links for congestion.
7. Compare available carrier paths.
8. Look for unnecessary public routing or network hops.
9. Measure application processing separately from network delay.
10. Reconsider facility location only if the results show that distance or routing is materially contributing to the problem.
Do these checks in this order so you do not pay to change infrastructure before identifying the fault.
More bandwidth will not shorten a poor route. A new carrier will not repair an overloaded database. Moving the servers will not help if the latency originates in a remote application dependency.
Measure first, then change the component that is actually responsible.
What to Fix First When Colocation Latency Is Too High
Start with the endpoints that matter and establish how traffic actually travels between them.
If latency is consistently high, investigate distance and routing. If it rises under load, look for congestion. If network measurements remain stable while the application slows down, move the investigation further up the application stack.
Once you know where the delay starts, you can change the part of the path that is actually responsible. That might mean additional capacity, a different carrier route, a private connection, an architecture change or, where distance is demonstrably part of the problem, a different colocation location.
We treat connectivity as part of the infrastructure design rather than something to consider only after equipment is installed. If latency is affecting an existing deployment, or you are planning infrastructure where network response time matters, <u>speak to us about your connectivity requirements</u>, and we can look at the network considerations alongside the wider colocation environment.
Meta Title: How to Improve Network Latency in Colocation | Carbon-Z
Meta Description: Improve colocation network latency by measuring routes, congestion, carrier paths and application delay, then fix the part of the network causing the issue.
Focus keyword: how to improve network latency in colocation
URL Slug: how-to-improve-network-latency-in-colocation
Featured image
Alternative text: Network engineer reviewing latency and routing performance on monitoring screens.

%20--%3e%3csvg%20version='1.1'%20id='Layer_1'%20xmlns='http://www.w3.org/2000/svg'%20xmlns:xlink='http://www.w3.org/1999/xlink'%20x='0px'%20y='0px'%20viewBox='0%200%20388.2%20150.6'%20style='enable-background:new%200%200%20388.2%20150.6;'%20xml:space='preserve'%3e%3cstyle%20type='text/css'%3e%20.st0{fill:%2304C7FD;}%20.st1{fill:%230068B5;}%20%3c/style%3e%3crect%20y='2.1'%20class='st0'%20width='28.1'%20height='28.1'/%3e%3cpath%20class='st1'%20d='M27.4,148.5V47.3H0.8v101.2H27.4z%20M204.2,149.5v-24.8c-3.9,0-7.2-0.2-9.6-0.6c-2.8-0.4-4.9-1.4-6.3-2.8%20c-1.4-1.4-2.3-3.4-2.8-6c-0.4-2.5-0.6-5.8-0.6-9.8V70.1h19.3V47.3h-19.3V7.8h-26.7v97.9c0,8.3,0.7,15.3,2.1,20.9%20c1.4,5.5,3.8,10,7.1,13.4s7.7,5.8,13,7.3c5.4,1.5,12.2,2.2,20.3,2.2L204.2,149.5L204.2,149.5z%20M357,148.5V0h-26.7v148.5H357z%20M132.5,57.2c-7.4-8-17.8-12-31-12c-6.4,0-12.2,1.3-17.5,3.9c-5.2,2.6-9.7,6.2-13.2,10.8l-1.5,1.9v-1.7V47.3H43v101.2h26.5V94.6v3.7%20c0-0.6,0-1.2,0-1.8c0.3-9.5,2.6-16.5,7-21c4.7-4.8,10.4-7.2,16.9-7.2c7.7,0,13.6,2.4,17.5,7c3.8,4.6,5.8,11.1,5.8,19.4l0,0v0.2l0,0%20l0,0v53.5h26.9V91C143.7,76.6,139.9,65.2,132.5,57.2z%20M316.5,97.7c0-7.3-1.3-14.1-3.8-20.5c-2.6-6.3-6.2-11.9-10.7-16.7%20c-4.6-4.8-10.1-8.5-16.5-11.2s-13.5-4-21.2-4c-7.3,0-14.2,1.4-20.6,4.1c-6.4,2.8-12,6.5-16.7,11.2s-8.5,10.3-11.2,16.7%20c-2.8,6.4-4.1,13.3-4.1,20.6c0,7.3,1.3,14.2,3.9,20.6c2.6,6.4,6.3,12,10.9,16.7c4.6,4.7,10.3,8.5,16.9,11.2%20c6.6,2.8,13.9,4.2,21.7,4.2c22.6,0,36.6-10.3,45-19.9l-19.2-14.6c-4,4.8-13.6,11.3-25.6,11.3c-7.5,0-13.7-1.7-18.4-5.2%20c-4.7-3.4-7.9-8.2-9.6-14.1l-0.3-0.9h79.5L316.5,97.7L316.5,97.7z%20M237.2,88.4c0-7.4,8.5-20.3,26.8-20.4c18.3,0,26.9,12.9,26.9,20.3%20L237.2,88.4z'/%3e%3cpath%20class='st1'%20d='M387.4,135.3c-0.5-1.2-1.2-2.2-2.1-3.1c-0.9-0.9-1.9-1.6-3.1-2.1s-2.5-0.8-3.8-0.8c-1.4,0-2.6,0.3-3.8,0.8%20c-1.2,0.5-2.2,1.2-3.1,2.1c-0.9,0.9-1.6,1.9-2.1,3.1c-0.5,1.2-0.8,2.5-0.8,3.8c0,1.4,0.3,2.6,0.8,3.8s1.2,2.2,2.1,3.1%20c0.9,0.9,1.9,1.6,3.1,2.1s2.5,0.8,3.8,0.8c1.4,0,2.6-0.3,3.8-0.8c1.2-0.5,2.2-1.2,3.1-2.1c0.9-0.9,1.6-1.9,2.1-3.1%20c0.5-1.2,0.8-2.5,0.8-3.8S387.9,136.5,387.4,135.3z%20M385.8,142.3c-0.4,1-1,1.9-1.7,2.6c-0.7,0.7-1.6,1.3-2.6,1.7s-2,0.6-3.2,0.6%20c-1.1,0-2.2-0.2-3.2-0.6c-1-0.4-1.9-1-2.6-1.7s-1.3-1.6-1.7-2.6c-0.4-1-0.6-2-0.6-3.2c0-1.1,0.2-2.2,0.6-3.2s1-1.9,1.7-2.6%20c0.7-0.7,1.6-1.3,2.6-1.7s2-0.6,3.2-0.6c1.1,0,2.2,0.2,3.2,0.6c1,0.4,1.9,1,2.6,1.7s1.3,1.6,1.7,2.6c0.4,1,0.6,2,0.6,3.2%20C386.5,140.3,386.2,141.3,385.8,142.3z%20M380.2,139.9c0.8-0.1,1.4-0.4,1.9-0.9s0.8-1.2,0.8-2.2c0-1.1-0.3-1.9-1-2.5%20c-0.6-0.6-1.7-0.9-3-0.9h-4.4v11.3h2.1v-4.6h1.5l2.8,4.6h2.2L380.2,139.9z%20M379.1,138.3c-0.3,0-0.6,0-1,0h-1.5v-3.2h1.5%20c0.3,0,0.6,0,1,0c0.3,0,0.6,0.1,0.9,0.2c0.3,0.1,0.5,0.3,0.6,0.5s0.2,0.5,0.2,0.9s-0.1,0.7-0.2,0.9c-0.2,0.2-0.4,0.4-0.6,0.5%20C379.7,138.2,379.4,138.3,379.1,138.3z'/%3e%3c/svg%3e)